


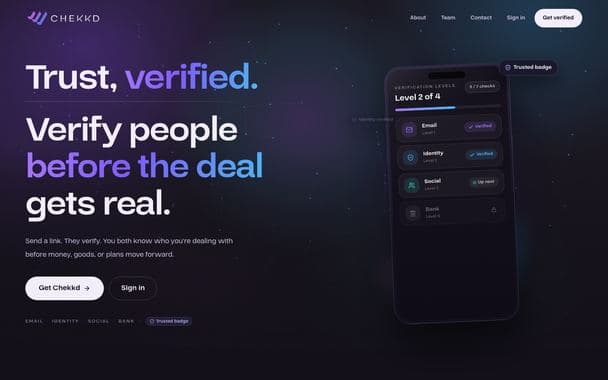
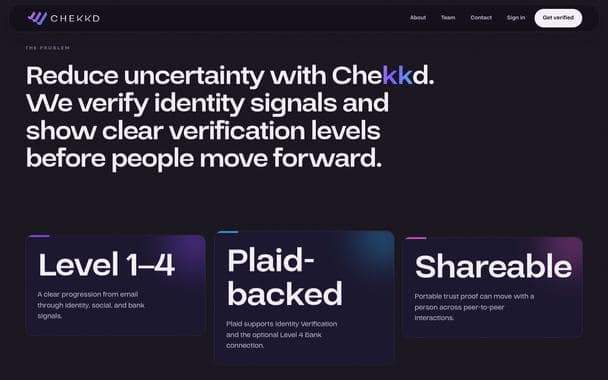
Identity verification for peer-to-peer deals: a four-level trust ladder with Plaid-backed ID checks, biometric liveness, and a portable TrustBadge.
Founded by Matthew Schwen in Franklin, TN and Lehi, UT.
AI at real scale.
I build LLM systems and agents that don’t fall over, with twenty years of running production behind me.
 Shipped and runningChekkd, RnBy, CarrierOS, CHESS, SaltBot, LaunchWatch
From the fiber up.
More than twenty years on call for every layer an AI system runs on: the fiber, the data center, the network, the platform, and now the AI on top.
2004to 2008
VCTEKMThe fiber and the NOC
Veracity Communications, TEKsystems, Mstar. Provo, UT
Started in a network operations center provisioning T1s, DSL and business phone systems, pulled fiber into new stores, then ran the core network for UTOPIA’s fiber-to-the-home service: data, voice and TV for more than 20,000 homes, on call around the clock.
2008to 2015

Data centers
Adobe. Lehi, UT
Seven years building Adobe’s own data-center routing, switching and firewalls, its Lehi campus network, fully meshed and non-blocking, and the networking inside and around its OpenStack cloud. On call for the network worldwide.
2015to 2017

Global operations
Symantec, then Alianza. Lindon, UT
Led engineering for Symantec’s global network operations: the escalation point for Severity One outages, root-cause analysis, and the routing standards that followed. At Alianza, a cloud voice platform for service providers, rebuilt the Ashburn data center on an Ansible-managed spine and leaf.
2017to 2019
The network as software
Adobe. Lehi, UT
Made the network self-service: one API call created a VLAN, reserved its subnet and DNS, and configured the switches and firewalls. Built Adobe’s first 100G backbone between data centers, a transit hub into AWS, and an auditor that finds configuration errors on its own.
2019to 2023

Reliability at ad-tech scale
The Trade Desk, Staff Software Engineer. Remote
Network reliability for an advertising platform answering billions of queries a day: a fully automated Cumulus and eBGP network across the WAN, AWS and Azure, Go-based BGP load balancers, and an automation platform on Kubernetes used across the company. Promoted to Staff, and hired the team.
2021to 2025

Founding a company
PortalCX, co-founder and CTO. Lehi, UT
Co-founded a customer-onboarding platform with my brother and a close friend, and wore every hat for four years: engineering, design, recruiting, fundraising and marketing.
2024to 2025

Automation and AI in the enterprise
Humana, Associate Director of Network Automation Engineering
Set Humana’s network-automation strategy and led its senior engineers across hundreds of vendors and regions: pipelines through Azure DevOps, ServiceNow and Ansible, a source-of-truth platform, and an AI co-pilot for network operations, unveiled in my ONUG keynote with Network to Code.
2025to now

 Schwen Scalability
Exabyte storage and AI products
Oracle, Chekkd, Schwen Scalability
Sr. Site Reliability Developer for Oracle Cloud Infrastructure Object Storage, at exabyte scale. Co-founder and CTO of Chekkd. And this practice: AI systems for founders, built on all of the above.
Computer science, University of Phoenix. Full résumé on request. Employers and roles held, not clients of Schwen Scalability. Company names and marks belong to their owners and are shown to describe where the work was done; they do not imply any endorsement, sponsorship, or affiliation.
Work
Products I founded, built for clients, or engineer inside as a technical partner. Every frame is a capture from the live site.
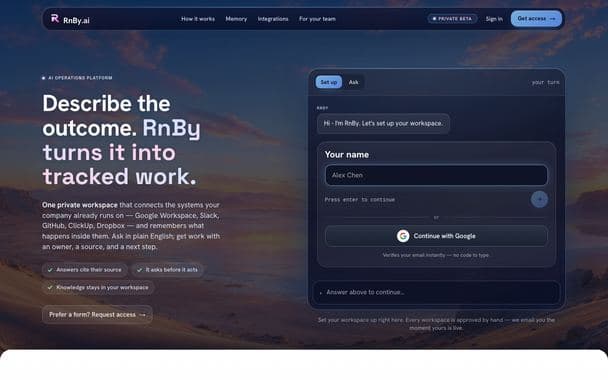
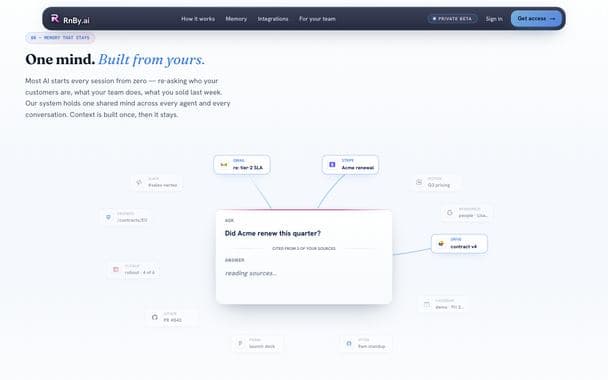
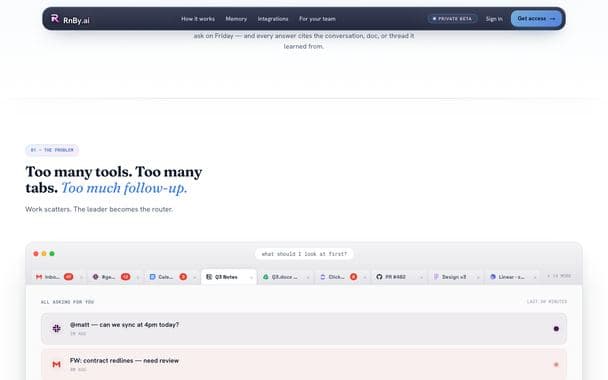
An AI operating layer for small business. Run your company from a conversation, with multi-agent routing, shared memory, and cited answers.
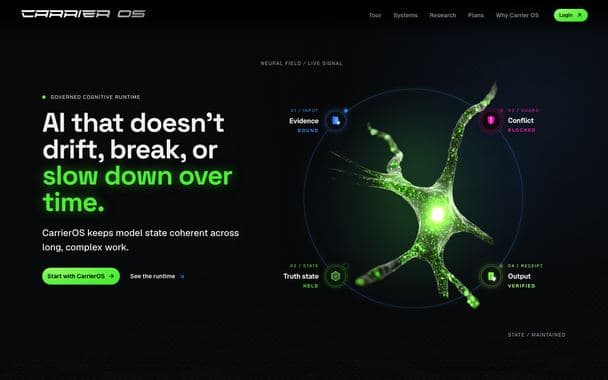
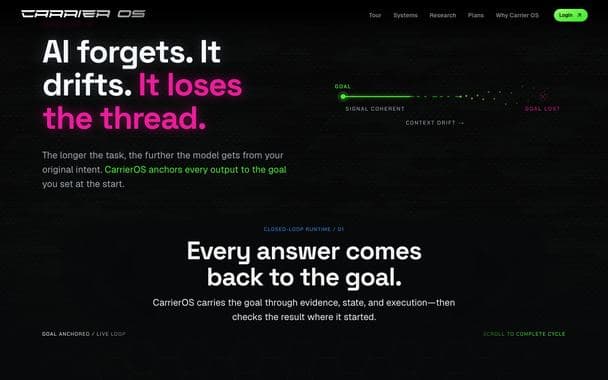
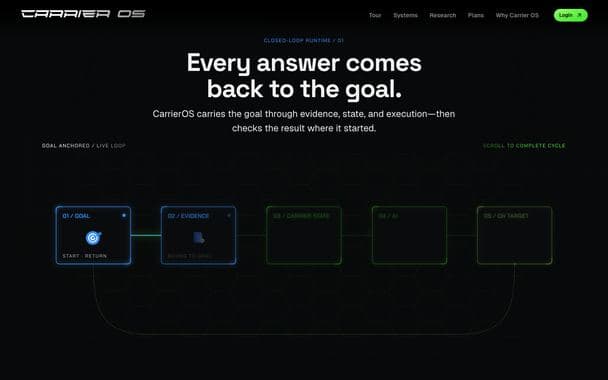
Inference control system that stabilizes long-running AI work: state-aware execution, persistent memory, multi-model orchestration.
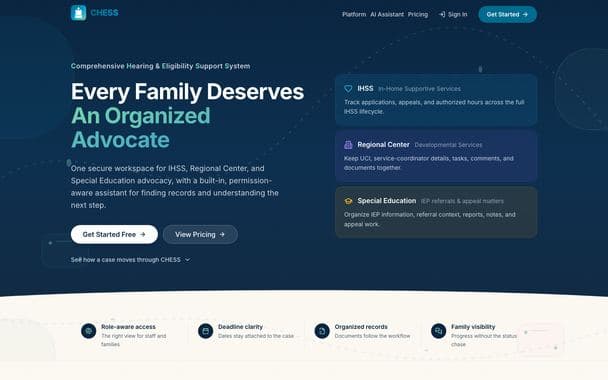
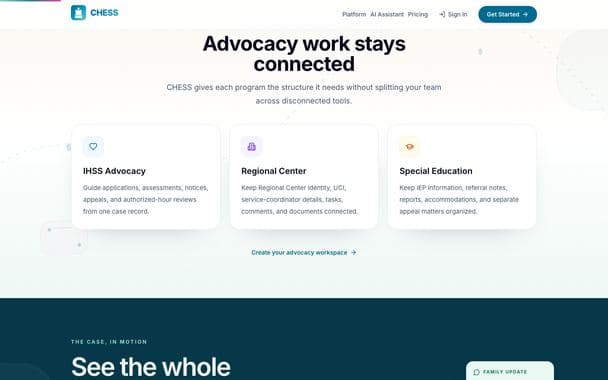
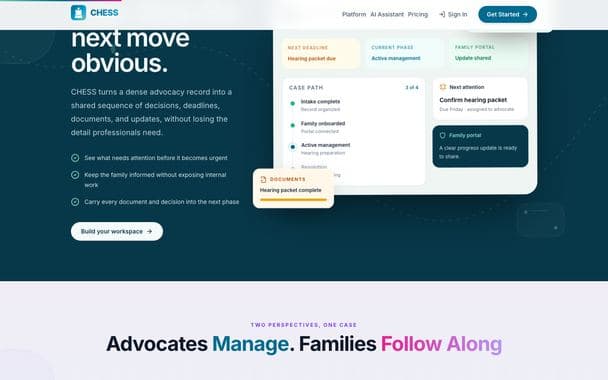
Case management for advocacy organizations: workflow state machines, a secure family portal, HIPAA-minded audit logging.
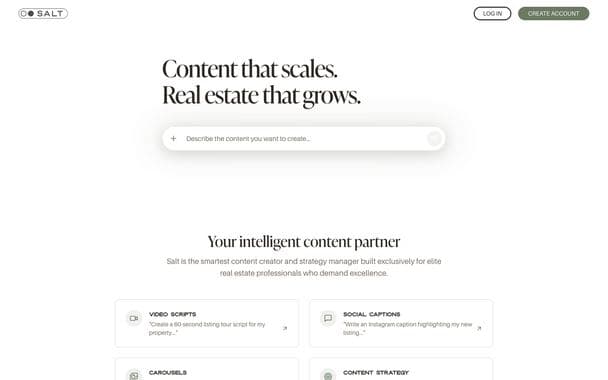
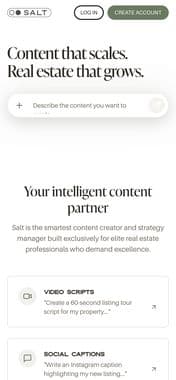
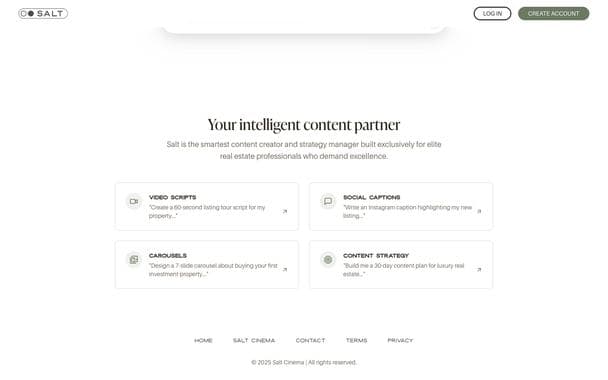
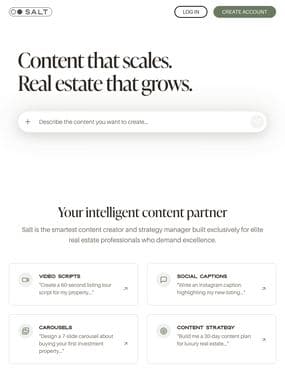
AI content strategist for luxury real-estate professionals, an AI consulting build for a media studio.
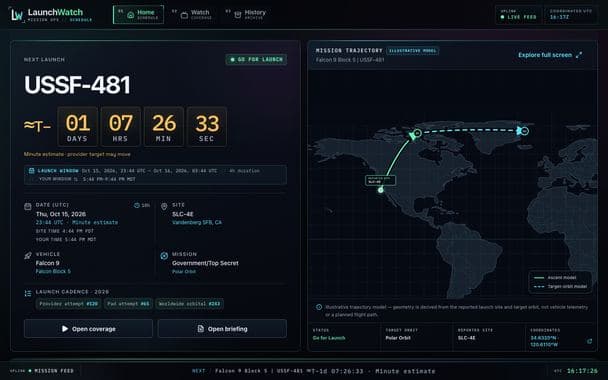
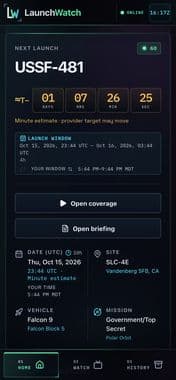
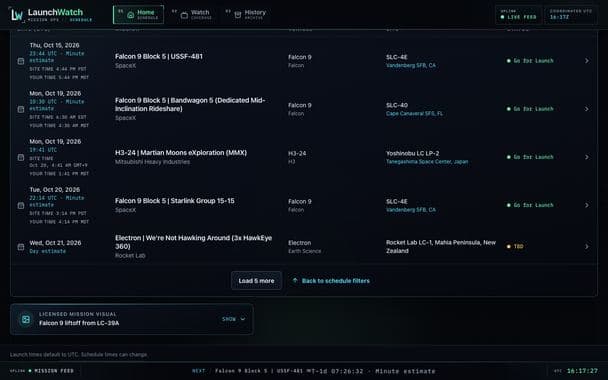
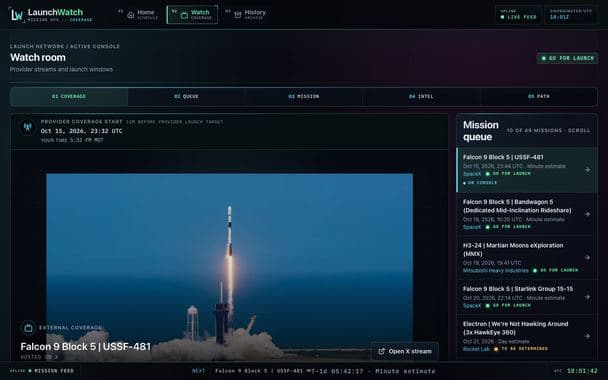
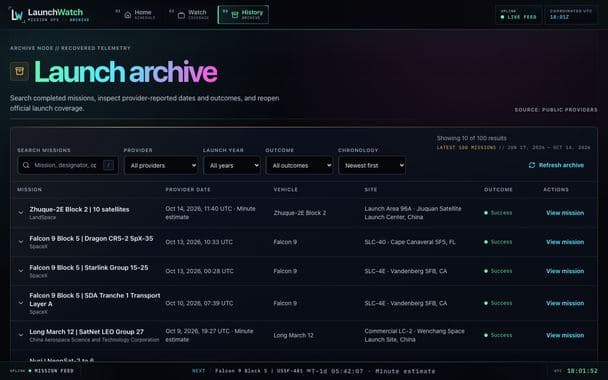
Real-time rocket-launch tracking across four live data sources: Launch Library 2, SNAPI, NASA, and Open-Meteo.
More builds
- Stakd Labz (opens stakdlabz.com in a new tab)DTC storefront. Built and shipped in one week
DTC storefront for research peptides: live product configurator, real-time pricing, bundles, checkout, fulfillment, and age-gated compliance.
- DYOR Wellness (opens dyorwellness.com in a new tab)Members platform. Built and shipped
Gated members-only wellness platform: private access requests, magic-link auth, and a compliance-heavy content model.
- Chekkd Lounge (opens chekkdlounge.com in a new tab)Events platform. Designed, built, running live
Link-in-bio profiles plus a full event suite: attendance, guest lists, email campaigns, and the database underneath.
Open source
- Claw Proxy (opens GitHub in a new tab)MIT, TypeScript. mattschwen/claude-max-api-proxy
OpenAI-shaped gateway into your authenticated Claude Code CLI: dynamic model routing, session resume, zero extra API key.
- Synapse (opens GitHub in a new tab)MIT, Python. mattschwen/Synapse
Autonomous AI agent for SRE and Ops on Semantic Kernel: dynamic incident-response planning, native code execution, vector memory, self-learning function reuse.
In The Beginning
A new AI product, in stealth
Founded and building now, heads-down. Details over a call; happy to demo under NDA.
Ask me about itMore under NDA, with references on request. Everything open source is at github.com/mattschwen.
Services
Every engagement is scoped the way an SRE plans a migration: explicit, measurable, reversible.
Under each service: where that kind of work was done. Employers and ventures, not clients.
Who you’ll work with
Systems don’t fail at the pieces. They fail where the pieces meet, so the joints are what I engineer first.
Where the auth meets the database. Where the agent meets the tool. Where the demo meets production. Twenty years of keeping systems alive, from fiber NOCs to exabyte-scale cloud storage, taught me that lesson on repeat, and Schwen Scalability is where I apply it for founders and operators.
The AI work isn’t prompt tinkering: retrieval with cited answers, multi-agent orchestration with shared memory, knowledge graphs over messy real-world documents, and evals that tell the truth. I bring an SRE’s paranoia to AI: measure it, cap its blast radius, make it reliable enough to bill for.
Two home bases, and on the road a lot.
- Home bases
- Franklin, TN and Lehi, UT
- Local time
- Central time in Franklin, Mountain time in Lehi
- In production since
- 2004
- Right now
- Sr. Site Reliability Developer, Oracle Cloud
Let’s make the pieces fit.
Tell the intake agent what you’re building. It verifies your email, reads your docs, and requests an intro call with Matthew.
Prefer email? matthew@schwen.me